


AI insights score and explanation

Updated on 15.09.26

10 minutes to read

Copy link
Overview
The AI insights score is a real-time, AI-generated risk score. It detects complex fraud patterns and anomalies that rules might miss while continuously retraining on your own transaction data to stay up to date. This guide covers how the score is calculated, how to read the explanation behind the individual score and how to control what your model learns from and when it goes live

What the AI insights score measures
The AI insights score calculates fraud probability on a scale from 0 to 100. A higher score indicates greater risk.
It is calculated using 1,100+ first-party data points, including device intelligence, behavioral patterns, velocity metrics, consortium signals (fraud history) and digital footprint characteristics.
What the AI insights score lets you do
The score supports both automated decisions and analyst review:
- Catch what your rules miss: the model reads correlations across 1,100+ signals that are too subtle to write a rule for and too slow to spot by hand.
- Decide in real time: the score is ready the moment a transaction or user is evaluated.
- Automate the clear-cut cases: feed the score straight into rules and alert triggers to approve and decline without analyst review.
- Understand every decision: select Explain beneath the score or in the AI summary to see exactly which signals pushed it higher or lower.
- Stay current as fraud tactics shift: model training runs weekly on your own data, and you can start a training run yourself whenever your fraud patterns change or your label quality improves.
- Review before it goes live: every training run produces a downloadable explanation and evaluation report, comparing the candidate model to the one in production, before anything changes.
- Govern deployment: models are held for review by default, so none reaches production without your explicit approval unless you switch automatically-triggered runs to automatic deployment. Every configuration change, training run, deployment and restore is logged.
Because the AI insights score is a machine learning score, SEON highly recommends using labels and feedback loops to refine the model over time. See Labeling best practices.
What's behind the score
The model analyzes 1,100+ first-party fraud signals for each transaction. It looks at user behavior, device details, digital footprint signals and consistency across data points.
Some of the top features used in decisions include:
- Action type (e.g. login, purchase, registration)
- Email type (disposable or not)
- Number of linked social media accounts
- Proxy or VPN usage
- Screen resolution and browser settings
- Country and location mismatches
These features are weighted based on how much they influence fraud risk. The more influence a signal has, the more impact it has on the score. Each customer's fraud pattern is different, so the AI insights score's algorithm learns from all data signals and uses the relevant features in customer-specific models.
How to enable and interpret the AI insights score
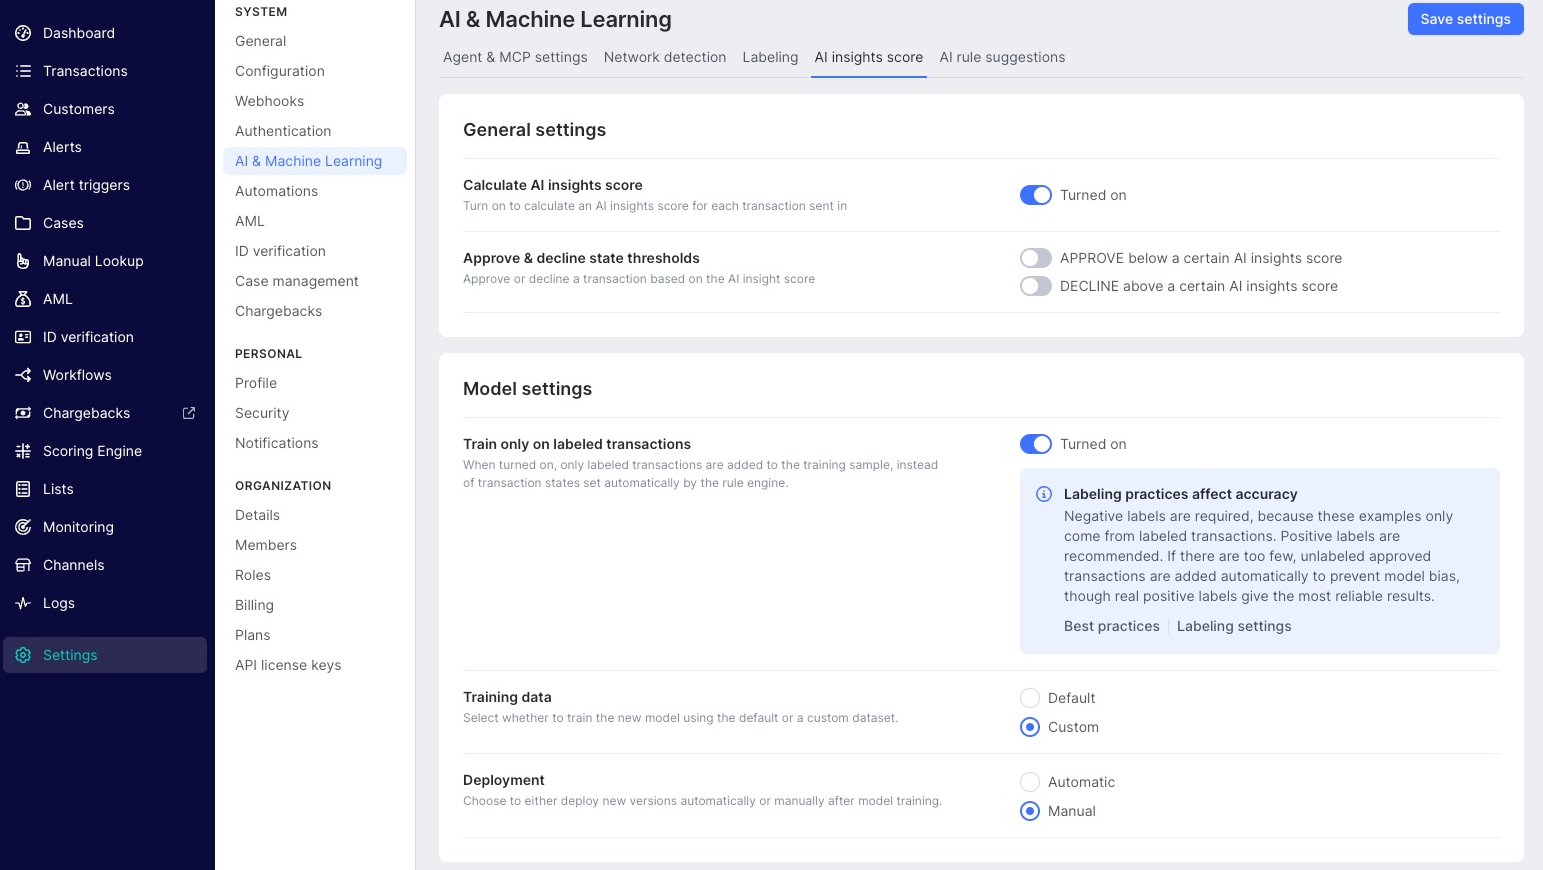
The AI insights score is turned on by default for new customers. Administrators can turn it on or off: go to Settings, then AI & Machine Learning (located in the System group), then select AI insights score tab. Once turned on, the score appears for new transactions and alerts.
The AI insights score complements SEON's rule-based fraud score. Rules remain transparent and under your control, while the AI insights score provides an additional layer of intelligence, reveals the rationale behind the score and catches patterns that static rules and human analysis might miss.
AI insights score explanation
Traditionally, AI and machine learning models are difficult to interpret for humans and are often unexplainable. SEON's AI insights score explanation provides an additional layer of depth behind it to provide visibility into the key factors that influenced each score.
The explanation makes each score auditable, so your team can act on it with confidence.
How to access the AI insights score explanation
There are two ways to access the AI insights score explanation:
- From the AI summary: Click the AI insights explanation link within the Next Steps in the AI summary panel.
- From the score breakdown: Beneath the AI insights score in the transaction or alert view, click Explain.
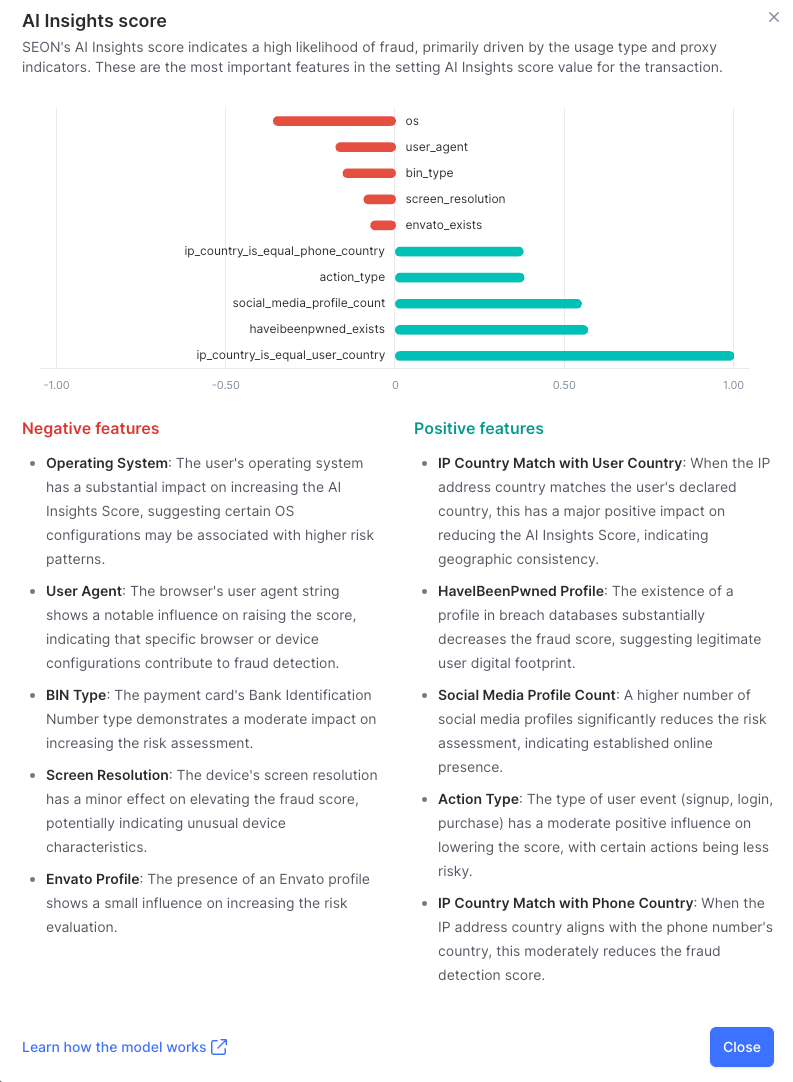
Both options open a breakdown of which data signals had the biggest impact on the score, divided into positive and negative contributors.

What is shows
The explanation behind the AI insights score uses a visual graph to display the top signals driving the score. Each factor is shown with a bar indicating how much it pushed the score up or down. The most impactful signals are listed at the top.
Examples of signals:
- Positive impact: Signals of legitimate transactions that could push the score lower include region language match, Netflix or Tumblr account existence, IP type, billing match.
- Negative impact: Signals of a risky transactions that push the score higher include use of uncommon payment methods, disposable emails, absence of social media accounts.
Each feature is accompanied by a short explanation, so you understand what it means and why it mattered in this decision.
Benefits
The AI Insights score explanation bridges the gap between AI and machine learning and human understanding, bringing trust to AI-powered fraud detection.
- Transparency: You no longer have to guess why a score is high or low
- Confidence: Analysts can see the logic behind decisions
- Better decisions: Knowing what’s driving risk helps focus investigation time
From the base model to your own trained model
Getting started with the base model
When you first start using SEON, your account does not yet hold enough of your own data to train a customer-specific model. The base model scores your transactions accurately from day one instead.
The base model is trained on an anonymized set of transactions from across SEON's customer base. Once your account reaches 1,000 events, with at least 100 in the DECLINE state and 100 in the APPROVE state, SEON starts training a model on your own data. When training succeeds, the model list shows your first customer-specific candidate model, which you can deploy to production.
How to provide training data to the custom AI insights model
There are two ways to feed the model:
- Submit data via the Fraud API and use rules to create approve and decline decisions, set by rules or manually.
- Label transactions using the Label API to train the model on real-world outcomes.
Prerequisites for training your own model
Before you can configure how and when your model retrains, your account needs:
- Your account must use Label API v2 to submit verification feedback to SEON. Accounts on the deprecated Label API v1 cannot access these settings. To check which version you are on, go to Settings, then AI & Machine Learning, then Label settings.
- The Calculate AI insights score setting must be turned on and in active use, since this setting controls whether a model is assessing and scoring transactions at all.
- You must hold the System settings role permission. Users without it cannot view or change these settings, and every change is written to the audit log against the user who made it.
How to configure what the model learns from
Three areas control how and when your model retrains: the model settings, the deployment settings and the model list.
Model settings
The model settings decide which transactions the model trains on, and over which period.
Train only on labeled transactions
Trains the model using only transactions you have explicitly labeled, through the SEON UI or the Label API, instead of also using automatic approve and decline outcomes. You must provide both positive (legitimate) and negative (fraud) labels.
Default training data
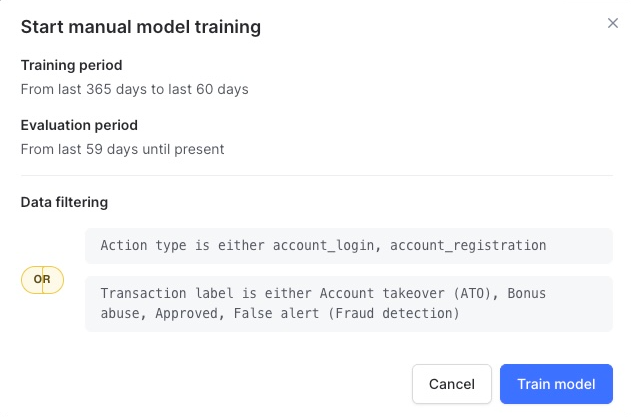
Select the default dataset, which is randomly selected transactions from the last 12 months, or a custom dataset scoped by time period and filters.
Custom training data
Fraud outcomes often aren't known right away. A chargeback might not surface for 45 days, a loan default might take 90 days or more.
If your training window includes transactions whose outcome isn't confirmed yet, the model learns from incomplete data. Custom training data lets you align the training window to how long your fraud outcomes take to mature.
Training and evaluation periods
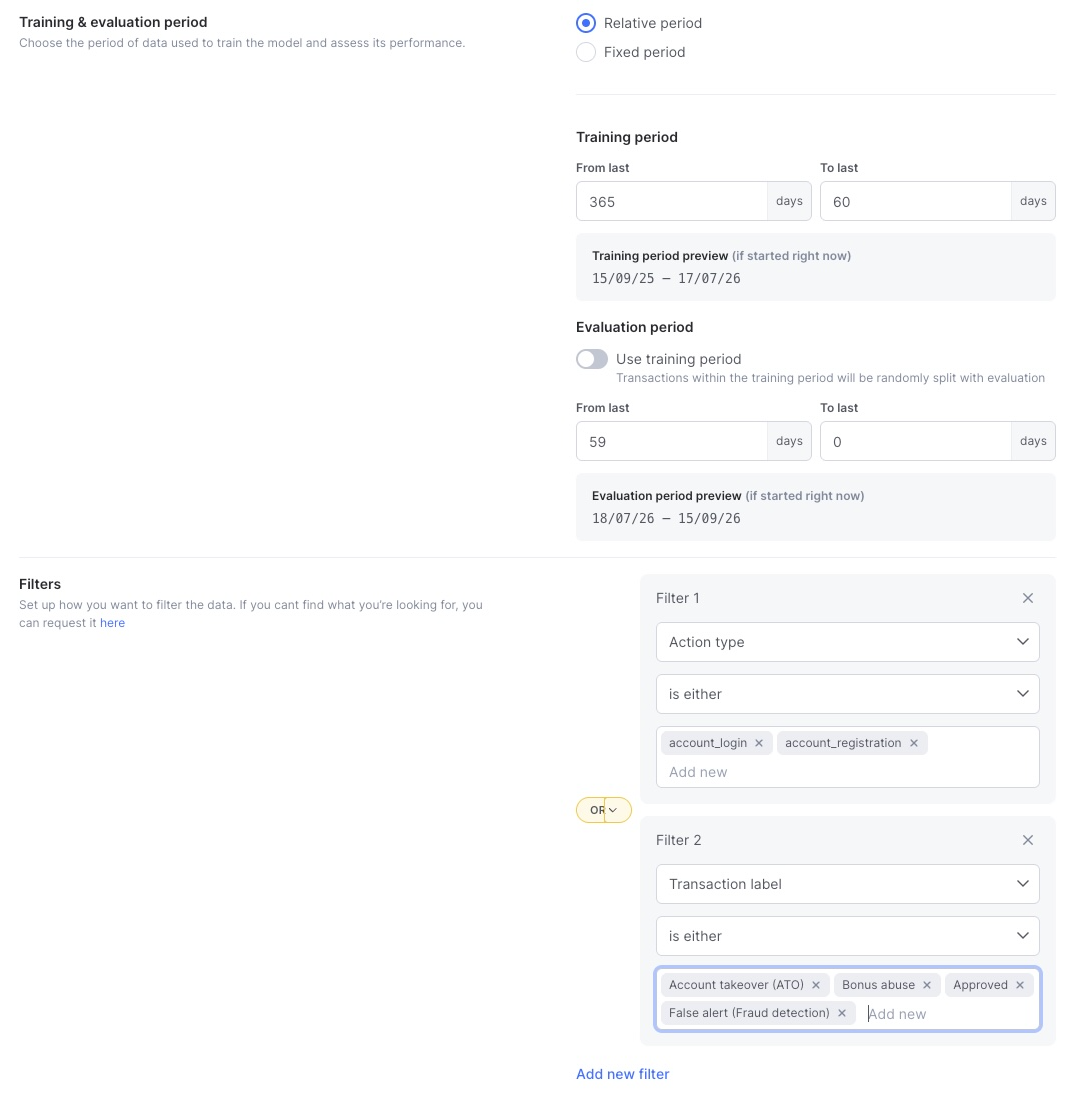
Define the training and evaluation periods as either a relative period using day offsets from today, or a fixed period with exact calendar dates.
For relative periods:
- From last [N] days sets how many days ago the period starts.
- To last [N] days sets how many days ago the period ends.
A live preview shows the exact dates that will be used the next time training runs.
Account for label maturity when you set these values. If your chargebacks take 45 days to appear in the majority of cases, set the end of the training period far enough back that labels are mature, for example To last 45 days. Training on transactions more recent than that, whose outcomes are still unknown, weakens the model's predictive accuracy.
The evaluation sample is selected at random from the training period by default. To use an independent period instead, turn on the Evaluation period toggle. An independent evaluation period cannot overlap the training period.
For a fixed period, the date pickers block invalid combinations. For a relative period, you'll see a warning if the two windows end up overlapping or incomplete. If you train with overlapping relative periods, your evaluation report won't show a comparison against the model in production.
Filters
Filters restrict training data to a subset of your transactions across all training and evaluation periods for your account training runs.
Available fields:
- Action type
- Transaction type
- Brand ID
- Merchant ID
- Affiliate ID
- Bonus campaign ID
- Label (Label API v2 only)
- All custom fields
Each filter condition takes a field, an operator (is, is not, is either, is none of) and a value. Add conditions with Add new filter and join them with AND or OR logic. If the field you need isn't listed, select Request a field to submit a request to SEON support.
Select Save settings in the top right to apply your changes. Selecting Train model also saves the current settings and uses them for that run.
How to train and deploy a new AI insights score model
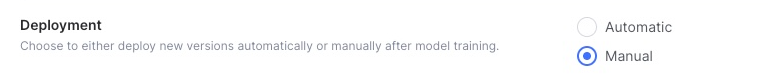
The Deployment setting decides what happens to a model once training finishes. Select whether trained models go live automatically once they pass evaluation, or are held as a candidate for you to review and deploy manually. It defaults to Manual.
This setting governs automatically-triggered training runs only, since a manually started run always produces a candidate for your review, regardless of this setting.
How to start a training run
Training runs automatically on a weekly schedule. You can also start a training run manually at any time, using your current customer training data settings.
What to expect from a manual run:
- A manual run can take up to 12 hours and takes priority over any queued automatic run.
- Only one manual training run can be in progress at a time. The Train model button is disabled while a run is in progress.
- A manually started run always produces a candidate for you to review and deploy yourself, even if the deployment settings above are set to automatic. This protects production from model changes without your review and approval.
Once started, you'll see a confirmation that training has begun. You don't need to keep the page open while it runs.
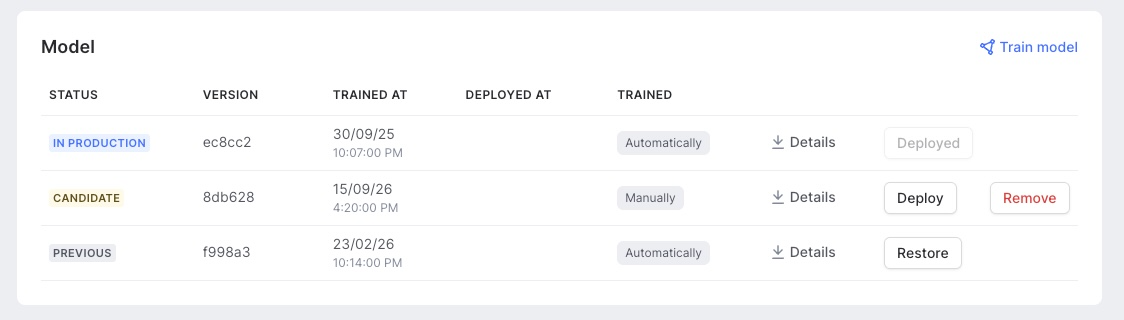
Model list
The model list shows every version of your model: any run that is training, candidate versions awaiting your review, the one live in production, past versions kept for rollback, and any manual training run that failed.
Each version's status is one of:
| Status | What it means |
| Training | The model is actively learning from your configured training data. |
| Candidate | A trained model that hasn't gone live yet. Candidate models are evaluated against real traffic in the evaluation period you defined, but never influence the score your transactions actually receive. Only your production model's score is used until you choose to deploy a candidate. A maximum of 5 candidates are kept in the list, for up to 60 days. When a sixth candidate is trained, the oldest is removed. |
| In production | The model used to score your live transactions. |
| Previous | An earlier version, kept so you can restore it later. |
| Failed | A manually started training run that didn't complete successfully. |
The Trained column shows whether a version was produced automatically or manually, and Details links to that version's performance report.
How to deploy a candidate model
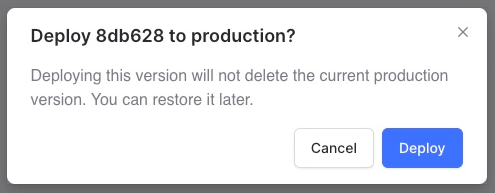
To put a candidate model into production:
- Find the candidate in the model list.
- Select the Deploy button.
- Confirm it has been deployed by checking the Status column, which changes to In production.
Deployment completes within a few minutes. The production model keeps scoring transactions until the new model is live.
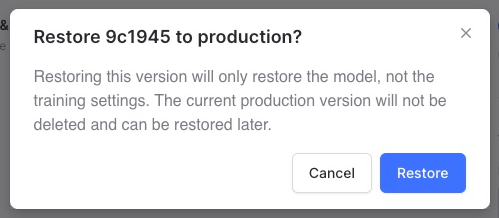
How to roll back an AI model from production
To roll back, find the version you want back in production in the model list and select Restore on its row. Your training and deployment settings stay unchanged, and the version you replace becomes the new Previous entry, ready to restore again if needed.
Model evaluation reports
Every completed training run produces two downloadable outputs, delivered in a ZIP package, from the Details link on its row in the model list above.
The model evaluation report (PDF) covers:
- A model summary and the training settings used, including period, evaluation window, filters, transaction count and labeled transaction ratio.
- The top features driving the model's decisions, each with an importance value and a plain-language explanation of what it captures.
- Performance metrics, including area under the curve (AUC), precision-recall AUC (PR-AUC), precision, recall, accuracy and F1, compared against the model in production.
- Those same metrics broken down by score threshold, including a version expressed in monetary terms, so you can see the monetary impact of a threshold choice rather than the transaction count alone.
The evaluation dataset CSV contains the transaction IDs in the evaluation sample, their states, labels, and both the production model's and the candidate model's score for each one. Use it to run your own analysis against your own business benchmarks
How to read the metrics
| Metric | Description |
| AUC (ROC) | Measures how well the score separates fraud from legitimate transactions across all thresholds. 1.0 is perfect and 0.5 is random. |
| PR-AUC | Summarizes the precision-recall trade-off across all thresholds. More informative than AUC (ROC) when fraud cases are a small share of all transactions. |
| Precision | Of all transactions flagged as fraud, what fraction actually were fraud. Low precision means many legitimate transactions are blocked, which means high customer friction. |
| Recall | Of all actual fraud transactions, what fraction were caught. Low recall means fraud slips through. |
| F1 score | A single number combining precision and recall, useful when both matter equally. |
| Accuracy | Fraction of all predictions, fraud and legitimate, that were correct. Can be misleading when fraud is rare, since always predicting legitimate can still score high. |
| EUR recall | Of the total EUR value of all fraud transactions, what fraction was caught at this threshold. Directly measures loss prevention. |
| EUR precision | Of the total EUR value blocked as fraud, what fraction was actually fraud. The remainder is a proxy for the financial cost of customer friction. |
| EUR F1 | A single number combining EUR recall and EUR precision. |
| Net lift (EUR) | EUR saved by catching fraud minus EUR lost to blocking legitimate transactions. Positive means the threshold creates net value versus approving everything. |
Notifications
Two notifications tell you how a training run ended:
- AI insights score model is ready for deployment, when a run with manual deployment finishes successfully.
- AI insights score model training failed, when a run fails.
Both are available in-app and by email, and each user turns them on or off under AI updates and suggestions in their notification settings. These notifications are configurable in Settings, then Personal, then Notifications, in the AI updates and suggestions section.
Audit log
Every model governance action, such as saving settings, starting a training run, deploying a model and restoring a model, is written to the audit log with a timestamp and the name of the user who performed it. To view the full history, go to Logs, then User Activity Log.